


Wikimedia asks court to rule AI training fair use, but not chatbot copying
The Wikimedia Foundation wants the judge in The New York Times’ copyright fight with OpenAI to split the question in two. Training an AI model on copyrighted work is likely fair use, it argues. A chatbot that copies websites to answer a user’s question is likely not. The foundation runs Wikipedia. On Thursday, it asked […] This story continues at The Next Web
Read original article on The Next Web →Related news
-
 ‘Obsession’ Director Curry Barker Drops a Freaky Horror Short Just in Time for Halloween
Entertainment
Movies
-
 Iowa and Ohio voters back AI safety measures over winning the AI race
Technology
AI
United States
-
 Global CO2 Levels Expected to Surge Thanks to This Super El Niño
Environment & Nature
Climate
Global
-
 Foxconn chairman says new OpenAI tie-up is in the works, Reuters reports
Technology
AI
Taiwan
-
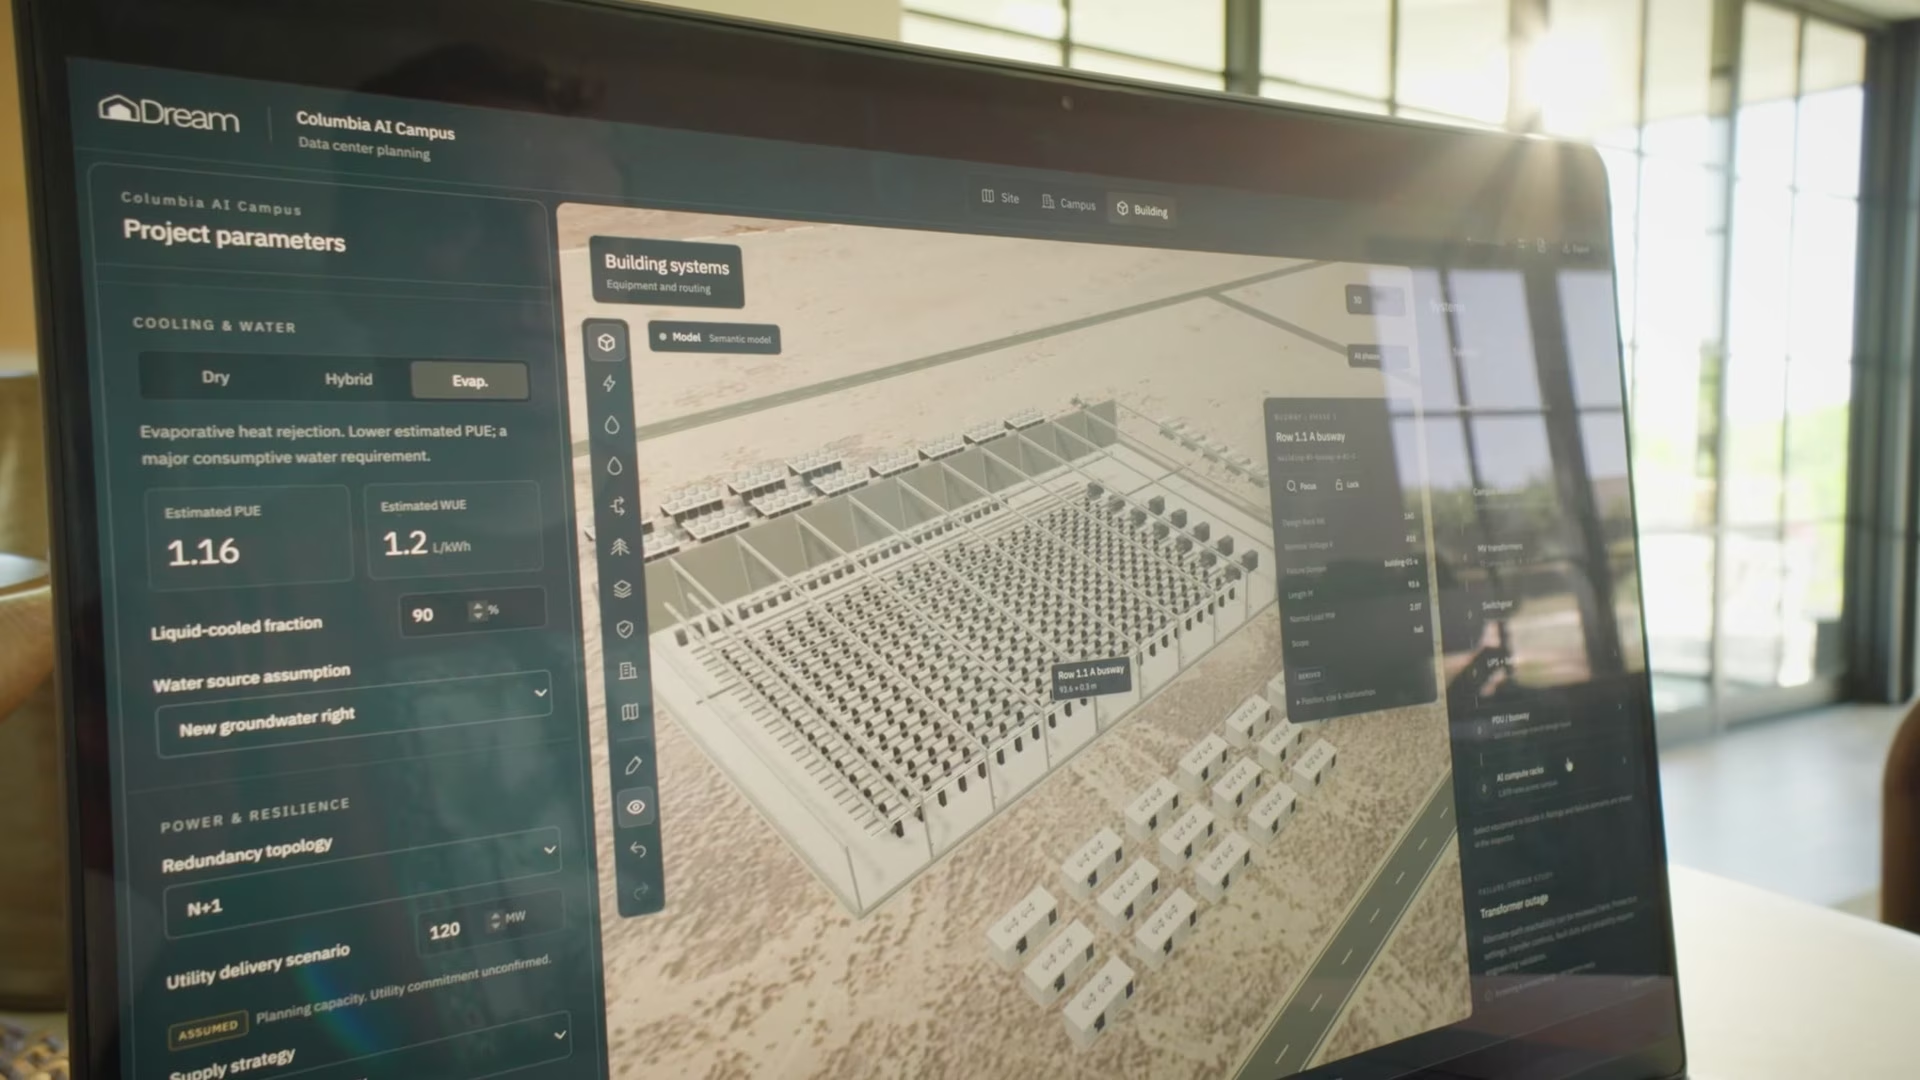 Ex-Palantir founders raise $17M for Dream’s AI building design models
Economy
Employment
Germany
-
 Reddit Will Force Users to Log In Soon
Technology
Social Media
-
 U.S. Military Thinks Hackers Defrosted All Its Ice Cream
War & Defense
Cyberwarfare
United States
-
 Amazon’s $42.4 Billion Cash Burn Delivers Final Blow In a Rough Week For AI
Technology
AI