
Show HN: Parsimony – an open-source benchmark for how much code AI models add
Existing benchmarks measure solve rate and token output/cost, but don't punish excess code, which makes a codebase harder to work with in the long term. I wanted to measure this since it matters most for long-term projects. Method: it takes the patches that benchmarks already publish (DeepSWE, SWE-bench Verified, SWE-bench Live) and counts "coding units": syntax elements like statements, calls,…
Read original article on Hacker News: Front Page →Related news
-
 Disney Accused Character.ai of Copyright Infringement. Now It’s Bidding on the Bankrupt Startup’s Assets
-
 7 Essential Marketing Strategies for Retailers
-
 PostEra (YC W20) Is Hiring AI Researchers for Drug Discovery
-
 Mark Zuckerberg Fumbled a Pint on Camera. How Guinness Won Millions in Free PR Without Lifting a Finger
-
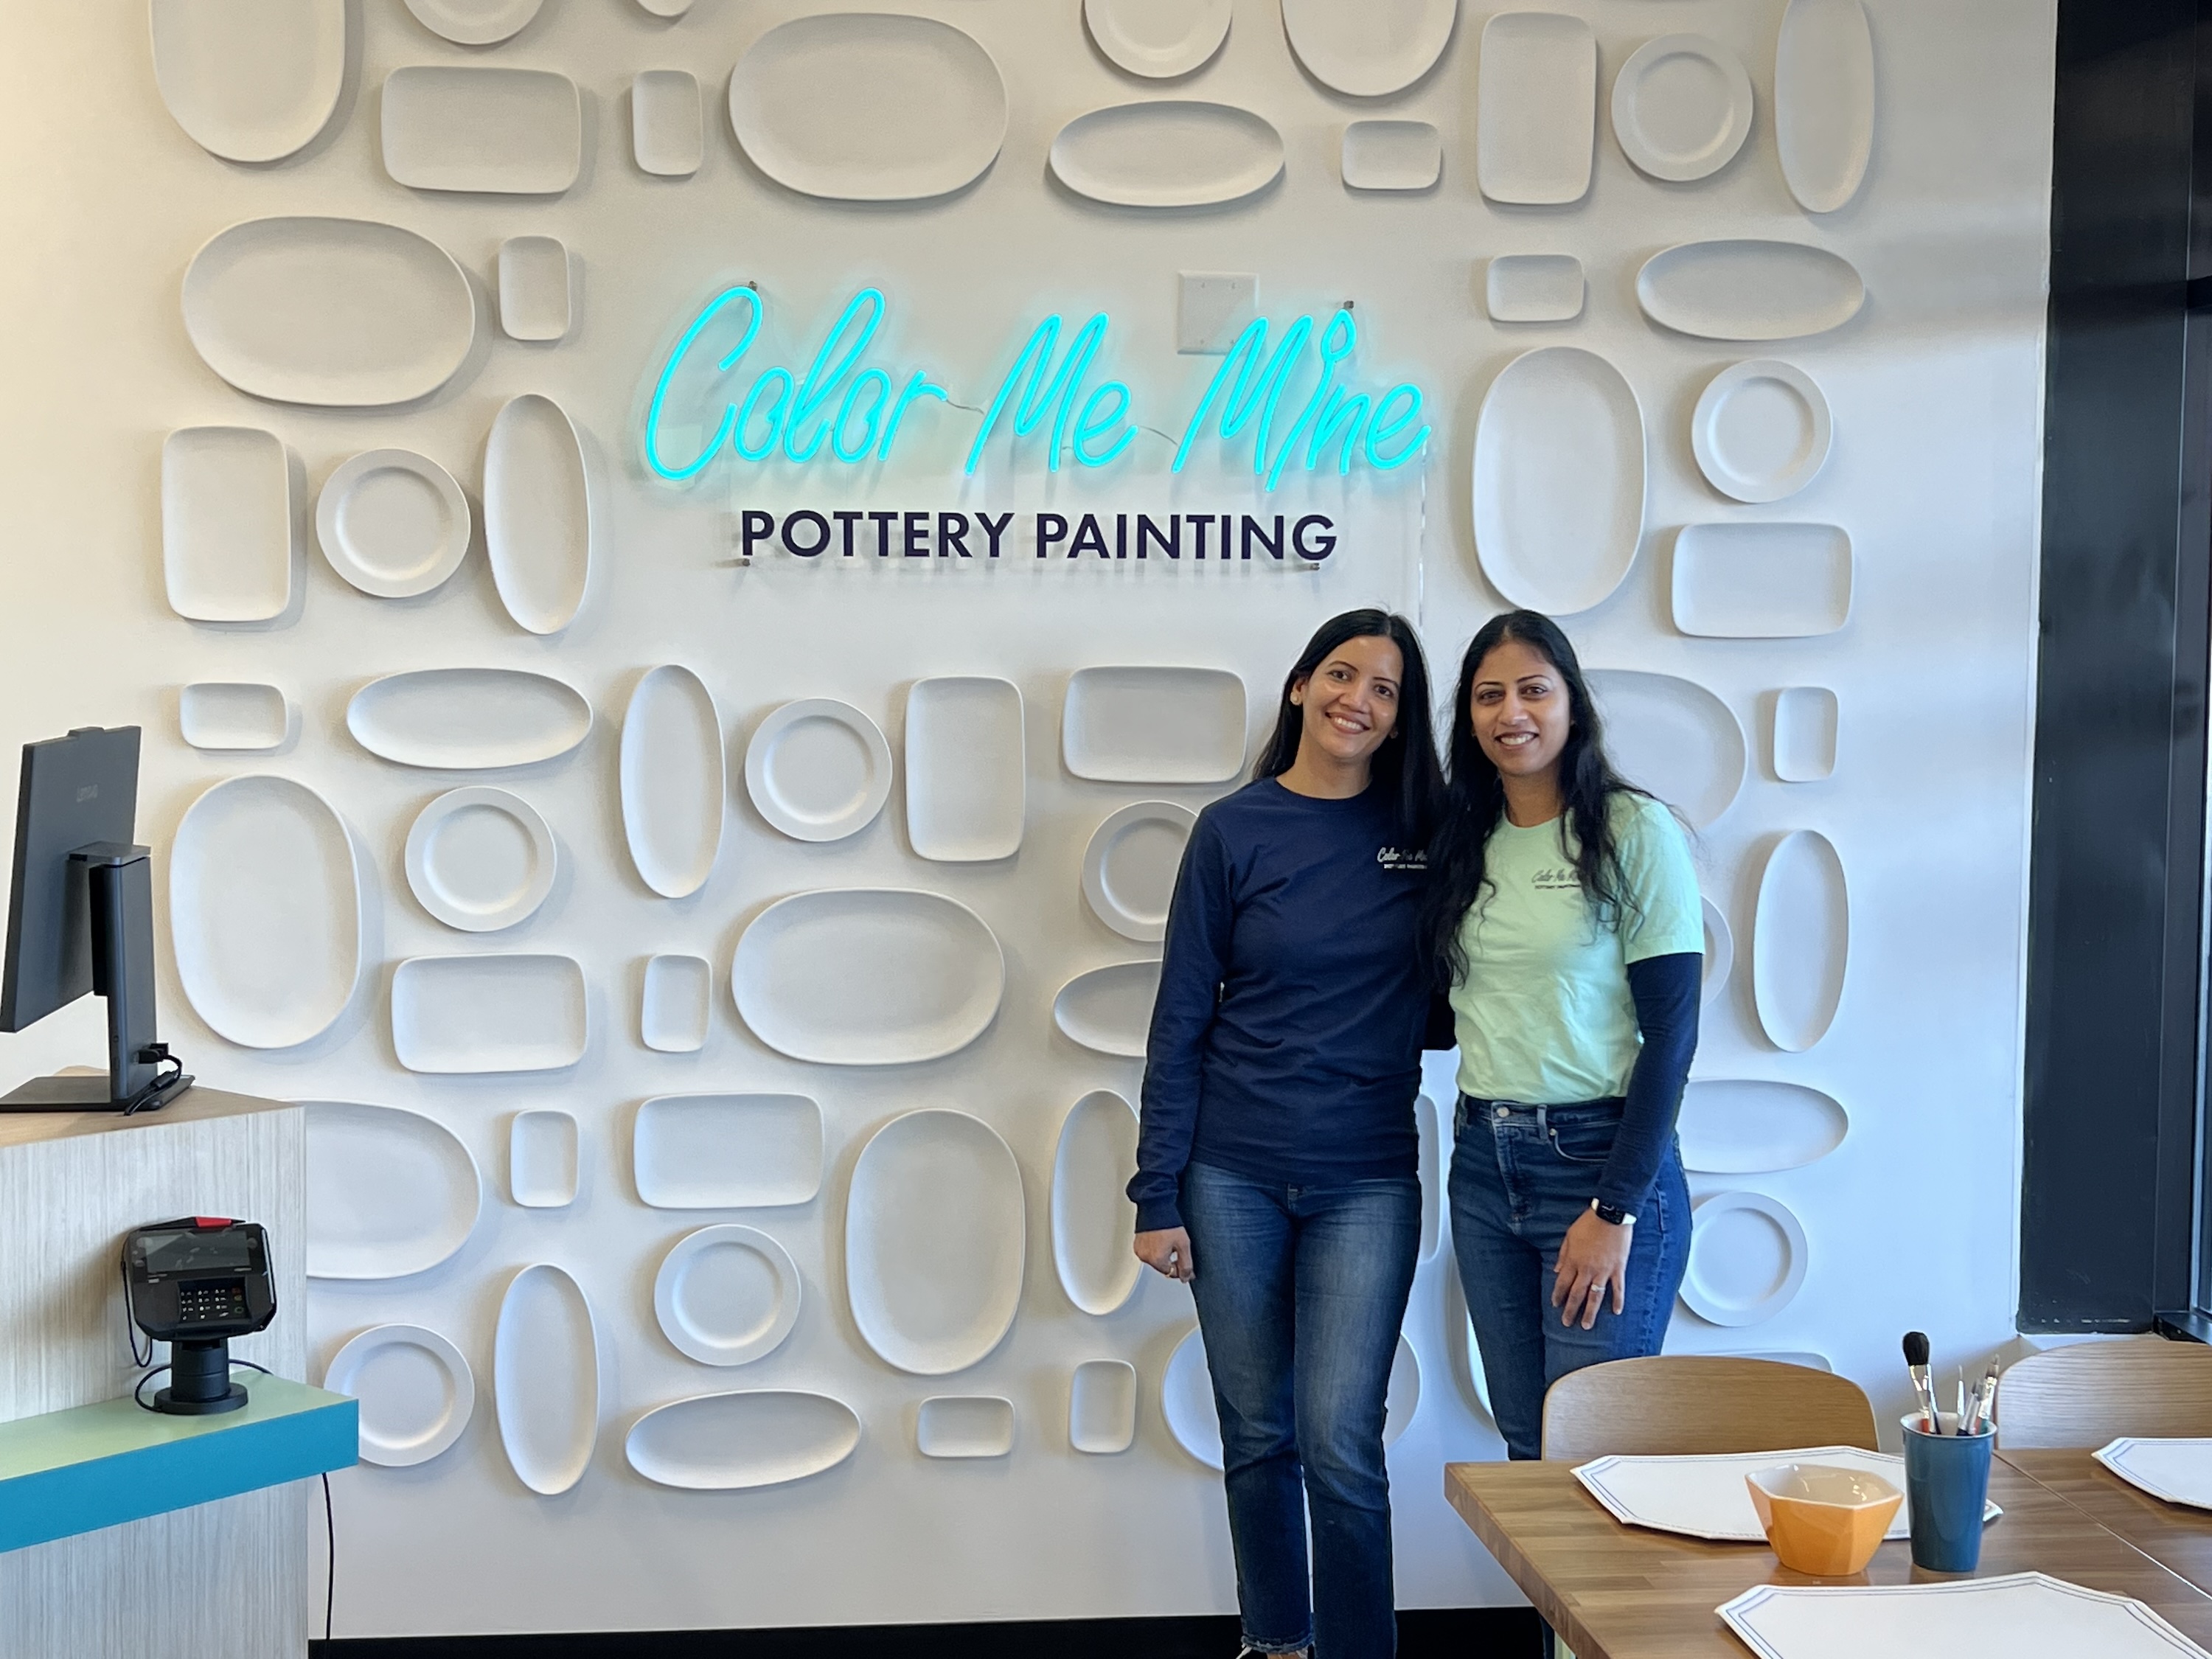 This Former Engineer and Preschool Teacher Teamed Up to Start a Creative Business: ‘Haven’t Regretted Choosing a Franchise.’
-
OpenAI engineer arrested in bugging of executive conference room
-
Why do you think people have such a hard time taking responsibility
-
 What Really Separates Successful CEOs From the Rest — A Private Equity Founder’s Unfiltered Take